Sept. 18, 2026
What to know about Anthropic’s new watermarking on AI text
Share this story
Anthropic, the company behind the large language model Claude, is rolling out a new method of watermarking AI-generated text. The process involves the use of a pattern of favored word choices that can be recognized by software while remaining undetectable to human readers.
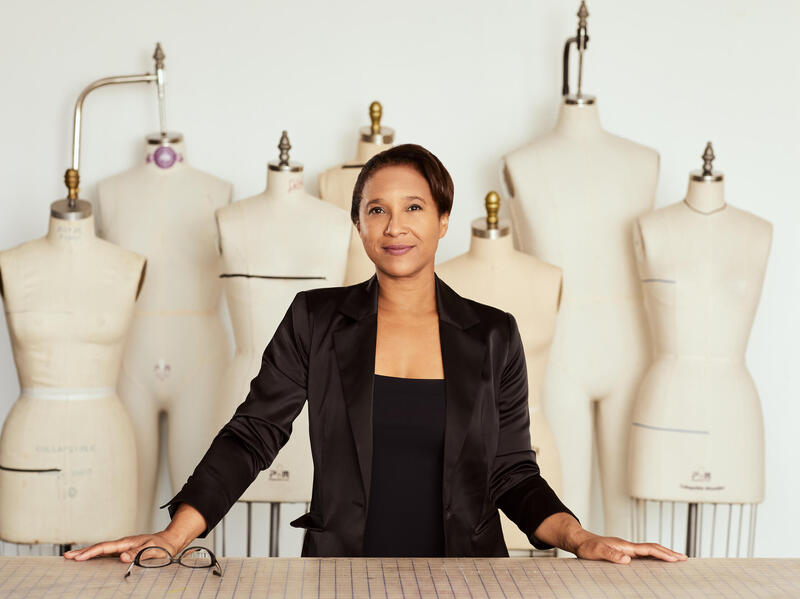
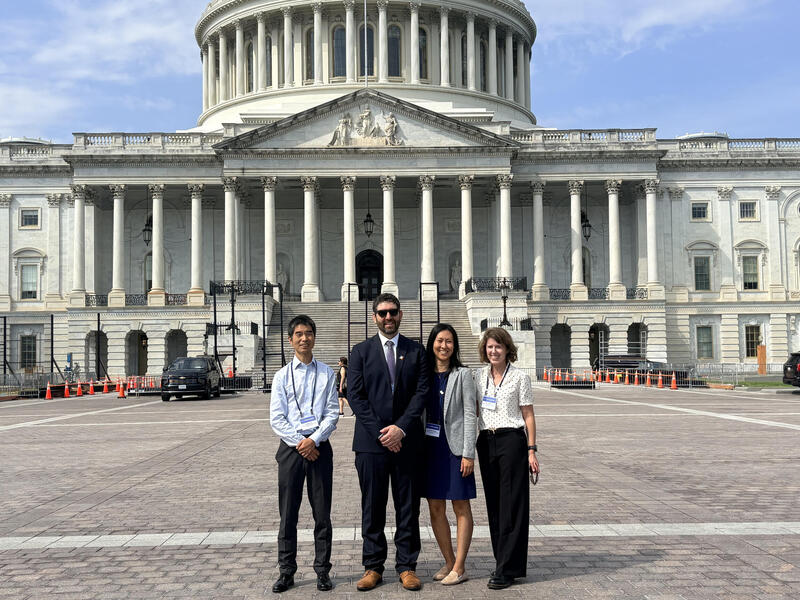
Hong-Sheng Zhou, Ph.D., associate professor in the Department of Computer Science at the Virginia Commonwealth University College of Engineering, is a cryptography expert with insight into the process of watermarking techniques.
Zhou shared what is driving the decision to watermark AI text and the potential impact that Anthropic’s approach will have on the AI landscape.
What does watermarking AI text have to do with cryptography?
More than 25 years ago, cryptographers started employing watermarking techniques to protect data. One example is copyright protection and digital rights management, where production houses would embed specific codes into the data on a DVD, for example. If that disk was illegally copied or its data extracted, the embedded watermark could provide evidence that helps identify where the copied content came from. It’s kind of like a fingerprint in the code that tells you where something came from.
Why would you watermark AI text?
One of the primary drivers is the European Union with its Artificial Intelligence Act, which has goals that include more transparency of what is AI generated and disclosing when AI is employed for a task.
But there is another side to this too – privacy, fairness and the appropriate use of detection. A watermark can provide evidence that an AI system may have been involved in producing content, but that evidence can easily be overinterpreted. Should we have the ability to use these tools without submitting to a verification test? What if the content is not AI generated, or employs a light use of AI, and the detection tool returns the wrong result?
Consider a foreign language speaker who is seeking employment. If they use AI to help bridge the language barrier and compose their resume but the employer rejects their application because AI tools were detected, is that fair?
Industry discussions are centered around topics like these and finding a balance between the perspectives. We need better awareness of things like deepfakes, and tools to detect them, but also need to consider individual users looking to use tools with no ill intent.
How do you go about watermarking text?
Claude, Gemini, ChatGPT and other large language models work by predicting what comes next in a response. Technically, the model predicts the next token — roughly speaking, a word or part of a word — based on an input, or prompt. As the AI works, there are several plausible choices for what comes next, and the large language model assigns scores or probabilities to those choices. The higher the probability assigned to a token, the more likely it is to be selected as the next word in the AI’s response.
Watermarking this kind of output is difficult because it’s dynamically generated. Static DVDs contain information that doesn’t change, so encoding it with a recognizable fingerprint is relatively easy. Multimedia file types also have places where you can hide the watermark to make it unobtrusive, but text generated by AI can't hide a watermark in that way because raw text doesn’t have places to store additional information.
What’s being done to watermark text is biasing the AI’s next word choice based on a secret key value. The goal is to introduce the watermark without noticeably changing the content or meaning of the generated text. If you analyze a sufficiently long sample of text, a detector can estimate whether a particular AI system, such as Claude, was involved in producing it. That does not mean the detector can identify every kind of AI-generated text or determine which AI system produced arbitrary content. Detecting the watermark relies on secret cryptographic information controlled by the model developer. That means the developer also controls who can use the detection tool by, for example, offering a detection service or API to authorized users.
What are some challenges with this kind of technology?
First is that you need a sample of text. Generally, the more text you have, the more statistical evidence the detector has to work with. Very short passages can be difficult to assess. This is an issue if someone takes a piece of AI-generated text and edits it, leading to some part of the text not being recognized as AI-generated. It’s also possible to muddle the watermark by translating the text into another language and translating it back.
Because these tools are not perfect, a detection result should not be treated as definitive proof on its own. These kinds of detection tools might be used as one source of evidence in settings like assessing whether AI may have been involved in a student’s essay.
There is also a governance question. The company embedding the watermark may also control the tool used to verify it, so outside users have to rely on the provider’s own detection system. An important question is whether trusted third parties should eventually have ways to independently verify these claims.
Where is AI watermarking going next?
Right now we’re in the middle of a big social experiment. There are proponents for AI use, but also people pushing back against it.
This reminds me of the internet’s first years. File types on the early internet were simple HTML code and text and images, but as things grew more data types came. Different image formats, multiple coding languages, videos with multiple encoding schemes, it’s kind of polluted. Applying watermarks to content, however, may help reveal where some content came from or whether AI was involved in producing it.
We don’t know what the future holds, but one application of this technology may be to help distinguish content produced entirely by people from content generated or substantially modified by AI.
As AI-generated content becomes more common online, it will become increasingly important to know where training data came from. AI-generated data is not necessarily bad but repeatedly training models on poorly understood or low-quality AI-generated material can reinforce errors or biases. Knowing the origin of training data can help developers make better decisions about what data to use.
Watermarking is only one way of protecting digital content in the age of AI. Other techniques are designed to make certain kinds of AI training more difficult or less effective. Those approaches are different from watermarking: a watermark is primarily intended to leave a detectable signal or provenance marker, while other forms of data protection are designed to affect the training process itself. Data poisoning is another, separate idea in which manipulated training data is intended to influence the behavior of a model.
This story was originally published on the College of Engineering website.
Subscribe to VCU News
Subscribe to VCU News at newsletter.vcu.edu and receive a selection of stories, videos, photos, news clips and event listings in your inbox.